pro $24.99 per month
- access to all Manning books, MEAPs, liveVideos, liveProjects, and audiobooks!
- choose one free eBook per month to keep
- exclusive 50% discount on all purchases
- renews monthly, pause or cancel renewal anytime
lite $19.99 per month
- access to all Manning books, including MEAPs!
team
5, 10 or 20 seats+ for your team - learn more
Look inside
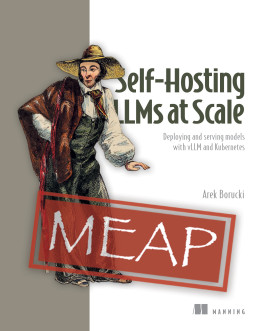
Public LLMs from vendors like OpenAI and Anthropic are impressive, but using them isn’t an option when you’re dealing with sensitive corporate information, regulated data, or private personal information (PPI). And for high-volume applications, costs quickly soar as usage grows. Self-Hosting LLMs at Scale, by Hugging Face platform engineer Arek Borucki, shows you how to move those workloads onto infrastructure your organization controls, using vLLM as the inference engine and Kubernetes as the platform. You’ll learn how to turn an open-weight model into a reliable internal service that your developers can call just like any commercial API.
Whether you’re bringing you LLM in-house for privacy, cost, compliance, or control, this book gives you the arithmetic, the engineering, and the operational discipline to do it well. It lays out the engineering path you need to serve open-weight models privately, reliably, and at a cost you can defend. Arek Borucki shows you how to apply what you already know about traditional platform engineering to serving LLMs as you transition a law firm from insecure public chatbots to a company-wide AI endpoint.
Every number in the book comes from a recorded lab session, and the early labs run on a free notebook GPU so you can reproduce the results without buying hardware. You’ll calculate GPU memory and cost for a model and workload before anything is deployed, choose an open-weight model using a golden set of questions built from your own work, and serve it behind an OpenAI-compatible API with streaming and sampling under your control.
To give you confiodenc—and proof—that your efforts are delivering positive results, you’ll benchmark the endpoint to find its real capacity limit, quantize larger models, and split one model across several GPUs or servers when it outgrows a single card. By the final chapters, you’ll run inference on Kubernetes with a gateway, quotas, monitoring, and safe rollouts.
Finally, you’ll see how to establish a model selection process that survives both staff turnover and new model releases, and explore vLLM internals that let you effectively tune a running system against real service level objectives. By the end, you’ll be operating a fully functional company platform, with model traffic routing, quota enforcing, full governance records, and even the ability to redirect to a commercial model via API when you need to.
Whether you’re bringing you LLM in-house for privacy, cost, compliance, or control, this book gives you the arithmetic, the engineering, and the operational discipline to do it well. It lays out the engineering path you need to serve open-weight models privately, reliably, and at a cost you can defend. Arek Borucki shows you how to apply what you already know about traditional platform engineering to serving LLMs as you transition a law firm from insecure public chatbots to a company-wide AI endpoint.
Every number in the book comes from a recorded lab session, and the early labs run on a free notebook GPU so you can reproduce the results without buying hardware. You’ll calculate GPU memory and cost for a model and workload before anything is deployed, choose an open-weight model using a golden set of questions built from your own work, and serve it behind an OpenAI-compatible API with streaming and sampling under your control.
To give you confiodenc—and proof—that your efforts are delivering positive results, you’ll benchmark the endpoint to find its real capacity limit, quantize larger models, and split one model across several GPUs or servers when it outgrows a single card. By the final chapters, you’ll run inference on Kubernetes with a gateway, quotas, monitoring, and safe rollouts.
Finally, you’ll see how to establish a model selection process that survives both staff turnover and new model releases, and explore vLLM internals that let you effectively tune a running system against real service level objectives. By the end, you’ll be operating a fully functional company platform, with model traffic routing, quota enforcing, full governance records, and even the ability to redirect to a commercial model via API when you need to.
what's inside
- Sizing GPU memory, cost, and capacity before you buy or rent hardware
- Choosing an open-weight model with license checks and acceptance tests
- Serving models with vLLM behind an OpenAI-compatible API
- Benchmarking, quantizing, and splitting models across multiple GPUs and servers
- Running LLM inference on Kubernetes with routing, quotas, monitoring, and safe rollouts
about the reader
Written for platform engineers, DevOps and SREs, backend developers, and technical leads. This book assumes comfort with Python and the command line but no prior experience with GPUs, CUDA, or ML theory.about the author
Arek Borucki is a Platform Engineer at Hugging Face, where he designs, operates, and scales the infrastructure behind the Hugging Face Hub—one of the largest ML platforms in the world, hosting millions of open-weight models. His work focuses on large-scale distributed systems and the practical side of running AI workloads in production.
related titles
related titles








choose your plan
pro
monthly
annual
$24.99
$249.99
only $20.83 per month
- access to all Manning books, MEAPs, liveVideos, liveProjects, and audiobooks!
- choose another free product every time you renew
- choose twelve free products per year
- exclusive 50% discount on all purchases
- renews monthly, pause or cancel renewal anytime
- renews annually, pause or cancel renewal anytime
-
![Self-Hosting LLMs at Scale]() Self-Hosting LLMs at Scale ebook for free
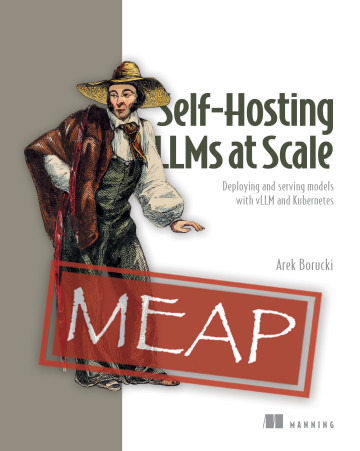 Self-Hosting LLMs at Scale ebook for free
team
monthly
annual
$49.99
$499.99
only $41.67 per month
- five seats for your team
- access to all Manning books, MEAPs, liveVideos, liveProjects, and audiobooks!
- choose another free product every time you renew
- choose twelve free products per year
- exclusive 50% discount on all purchases
- renews monthly, pause or cancel renewal anytime
- renews annually, pause or cancel renewal anytime
-
![Self-Hosting LLMs at Scale]() Self-Hosting LLMs at Scale ebook for free
choose your plan
pro
monthly
annual
$24.99
$249.99
only $20.83 per month
- access to all Manning books, MEAPs, liveVideos, liveProjects, and audiobooks!
- choose another free product every time you renew
- choose twelve free products per year
- exclusive 50% discount on all purchases
- renews monthly, pause or cancel renewal anytime
- renews annually, pause or cancel renewal anytime
-
![Self-Hosting LLMs at Scale]() Self-Hosting LLMs at Scale ebook for free
team
monthly
annual
$49.99
$499.99
only $41.67 per month
- five seats for your team
- access to all Manning books, MEAPs, liveVideos, liveProjects, and audiobooks!
- choose another free product every time you renew
- choose twelve free products per year
- exclusive 50% discount on all purchases
- renews monthly, pause or cancel renewal anytime
- renews annually, pause or cancel renewal anytime
-
![Self-Hosting LLMs at Scale]() Self-Hosting LLMs at Scale ebook for free
